
Greedy algorithms bet on the best-looking choice at every step. Dynamic programming breaks a problem into overlapping subproblems, solves each one once, and reuses the answers. Knowing which one to reach for is one of the most common interview and optimization questions, so this post walks through worked examples of both and ends with a simple way to choose between them.
Greedy vs. dynamic programming at a glance
| Greedy | Dynamic programming | |
|---|---|---|
| How it decides | Takes the best-looking option now and never revisits it | Solves every overlapping subproblem once, stores the results, and combines them |
| Guaranteed optimal? | Only if the problem has the greedy-choice property | Yes, whenever the problem has optimal substructure |
| Typical cost | Fast, often O(n log n) after sorting | Slower, with extra memory for the table |
| Classic examples | Interval scheduling, Huffman coding | Coin change, LIS/LCS, 0/1 knapsack, matrix chain multiplication |
Rule of thumb: if you can prove the locally best choice is always safe, go greedy. If you can’t, use dynamic programming. Jump to the greedy examples or the full trade-offs.
🌸👋🏻 Enjoying this post? Get the next issue of [ret]2read. Once a month, I’ll email you whatever’s on my mind, usually Apple security research, offensive security, open source software freedom, and operating system internals.
Greedy algorithms
Greedy algorithms make locally optimal choices at each step to (hopefully) achieve a global optimum.
A greedy algorithm is guaranteed to be optimal only when the problem has two properties: optimal substructure (an optimal solution contains optimal solutions to its subproblems) and the greedy-choice property (some locally optimal choice can always be extended into a globally optimal solution). When the greedy-choice property doesn’t hold, a series of locally optimal choices can produce a suboptimal answer. Two classic problems where greedy is provably optimal are interval scheduling and Huffman coding.
Interval scheduling
Selecting non-overlapping intervals to maximize the number of scheduled activities.
Interval scheduling is where the goal is to select the maximum number of non-overlapping intervals from a set of intervals. Here is a simple example.
Example
Suppose you have a set of activities, each represented by a pair of start and end times. The goal is to select the maximum number of non-overlapping activities.
In this example, the intervals are:
- (1, 3)
- (2, 4)
- (3, 6)
- (5, 7)
- (8, 9)
The algorithm sorts the intervals based on their end times and then iterates through them, selecting non-overlapping intervals. The selected intervals in this case would be:
- (1, 3)
- (3, 6)
- (8, 9)
These intervals do not overlap, and it is impossible to select more non-overlapping intervals. (3, 6) is chosen because it starts exactly when (1, 3) ends, which the code counts as non-overlapping. The output of the program would be:
selected intervals: [(1, 3), (3, 6), (8, 9)]Interval scheduling helps schedule tasks, where each interval represents a task’s start and end time, and the goal is to maximize the number of tasks that can be completed without overlapping.
Huffman coding
Building an optimal prefix-free binary tree for data compression.
Huffman coding is a variable-length encoding algorithm that efficiently represents data by assigning shorter codes to more frequently occurring symbols, reducing the overall amount of information needed for storage or transmission.
Huffman coding is like making a secret code for words, where we use shorter secret messages for words we say a lot, and longer secret messages for words we say less often, so we can save space and talk faster.
Example
Suppose we want to encode the message “ABRACADABRA.”
Step 1
Count the frequency of each character in the message.
- A: 5
- B: 2
- R: 2
- C: 1
- D: 1
Step 2
Create a priority queue (or a min-heap) based on the frequencies.
Priority Queue:

(1) C: 1

(2) D: 1

(3) R: 2

(4) B: 2

(5) A: 5
Step 3
Next, we build the Huffman tree by repeatedly combining the two least frequent nodes until only one node remains.
CD
Combine (1) and (2) to create a new node with frequency 2: CD.
Priority Queue:

(3) R: 2

(4) B: 2

(6) CD: 2

(5) A: 5
RB
Combine (3) and (4) to create a new node with frequency 4: RB. (CD also has frequency 2, so this tie could be broken differently; every tie-break produces an equally short encoding.)
Priority Queue:

(6) CD: 2

(7) RB: 4

(5) A: 5
CDRB
Combine (6) and (7), the two lowest frequencies left, to create a new node with frequency 6: CDRB.
Priority Queue:

(5) A: 5

(8) CDRB: 6
Huffman tree
Combine (5) and (8) to create the root of the final Huffman tree. Its frequency, 11, equals the length of the message:
      ABRACADABRA: 11
        0/      \1
       A: 5    CDRB: 6
              0/     \1
            CD: 2    RB: 4
           0/ \1    0/ \1
           D   C    R   B
Step 4
Lastly, we assign binary codes to each character based on the tree traversal. We assign 0 for left edges and 1 for right edges.
A: 0

B: 111

R: 110

C: 101

D: 100
The encoded message “ABRACADABRA” would be represented as the 23-bit binary string below, which matches the output of the code later in this post. A fixed-length code would need 3 bits per character for five symbols (33 bits), and 8-bit ASCII would need 88 bits:
01111100101010001111100This example represents the basic idea behind Huffman coding, where more frequent characters are represented with shorter codes, leading to a more efficient encoding of the original message.
Code
Here is a technical implementation example of Huffman coding.
Dynamic programming algorithms
Dynamic programming algorithms break a problem into overlapping subproblems and solve each subproblem only once, storing the solutions to reuse later.
Coin change
The coin change problem is a classic dynamic programming problem that involves finding the number of ways to make change for a given amount using a given set of coin denominations.
Here is an example in Python:
In this example, the function coin_change_ways takes a list of coin denominations (coins) and a target amount (amount). It uses dynamic programming to build a table (dp) where dp[i] represents the number of ways to make change for amount i. The function iterates through each coin denomination, updating the table based on the current coin.
For the provided example, it will output:
There are 5 ways to make change for 6 using the coins [1, 2, 5].This means five different combinations of coins can create the amount 6 using the given denominations [1, 2, 5].
Minimum change variation
The coin change problem can also refer to the minimum number of coins needed to make change for a given amount (video).
In this example, the function min_coins calculates the minimum number of coins needed to create 11 using coins with denominations [1, 2, 5]. The program would print the result as the output. If it is impossible to change the given amount, the function returns -1.
Longest increasing subsequence
Longest increasing subsequence (LIS) problems involve finding the length of the longest subsequence where elements are in increasing order. Dynamic programming solves each subproblem only once, which beats a naive recursive approach. Provided below is a pseudocode implementation for an LIS problem.
Pseudocode
Code
🌸👋🏻 Enjoying this post? Get the next issue of [ret]2read. Once a month, I’ll email you whatever’s on my mind, usually Apple security research, offensive security, open source software freedom, and operating system internals.
Longest common subsequence
Longest common subsequence (LCS) problems involve finding the length of the longest subsequence common to two sequences. Provided below is a pseudocode implementation for an LCS problem.
Want your company or product in front of [ret]2read readers?
One sponsor per issue →
Pseudocode
Code
Knapsack and its variants
Solving problems where items have weights and values, the goal is maximizing the total value without exceeding a weight limit.
The knapsack problem is a classic optimization problem with the goal of selecting a subset of items with maximum total value, subject to a constraint on the total weight. Here is an example:
Suppose you have a knapsack with a maximum weight capacity of 10 units, and you have the following items with their respective values and weights:
- Item 1: Value = 60, Weight = 5
- Item 2: Value = 50, Weight = 3
- Item 3: Value = 70, Weight = 4
- Item 4: Value = 30, Weight = 2
The goal is to determine the combination of items that maximizes the total value while keeping the total weight within the knapsack capacity.
In this 0/1 version of the problem, each item is either taken whole or left out. The optimal solution is to select Item 2, Item 3, and Item 4. The total value is 50 + 70 + 30 = 150, and the total weight is 3 + 4 + 2 = 9, which is within the knapsack capacity of 10. No other combination that fits does better; for example, Items 1 and 3 give 130, and Items 1, 2, and 4 give 140.
Multiple knapsack problem
One variant of the classic knapsack problem is the multiple knapsack problem. Instead of having only one knapsack to fill, this variant has multiple knapsacks, each with its own capacity constraint. The goal is to maximize the total value of items placed into the knapsacks without exceeding their individual capacities.
For example, suppose you have three knapsacks with capacities  ,
 , and
 , and a set of items with their respective values and weights:
| Item | Value | Weight |
|---|---|---|
| 1 | 8 | 4 |
| 2 | 10 | 6 |
| 3 | 15 | 8 |
| 4 | 4 | 3 |
The goal is to find the combination of items to include in each knapsack to maximize the total value while respecting the capacity constraints.
Formulation
Decision variables
Let  be a binary variable indicating whether item
 is placed in knapsack
 .
Objective function
Maximize the total value:

Constraints
Ensure that the total weight in each knapsack does not exceed its capacity:


and

Binary constraints
 for all and .
Each item can be placed in at most one knapsack:
 for all .
Matrix chain multiplication
Optimally parenthesizing the multiplication of matrices to minimize the number of scalar multiplications.
The goal of matrix chain multiplication is to find the most efficient way to multiply a sequence of matrices. The efficiency is measured by the total number of scalar multiplications needed to compute the product.
Here, a scalar multiplication is a single multiplication of two numbers. Multiplying a p×q matrix by a q×r matrix takes p·q·r of them.
Example
Let’s consider an example with three matrices: A, B, and C. The dimensions of these matrices are as follows:
- Matrix A has dimensions 10×20.
- Matrix B has dimensions 20×30.
- Matrix C has dimensions 30×40.
Here, we want to find the most efficient way to parenthesize these matrices for multiplication, minimizing the total number of scalar multiplications.
One possible parenthesization is as follows:
- Multiply A and B – the resultant matrix AB has dimensions 10×30.
- Multiply the result (AB) with C – the final result ABC has dimensions 10×40.
So, the sequence of multiplications is (A * B) * C.
If we parenthesize differently, such as (A * (B * C)), the dimensions would differ, and the total number of scalar multiplications would be higher. (A * B) * C takes 10·20·30 + 10·30·40 = 18,000 scalar multiplications, while A * (B * C) takes 20·30·40 + 10·20·40 = 32,000, so (A * B) * C is cheaper.
The key idea in matrix chain multiplication is to find the optimal parenthesization to minimize the total cost of multiplication.
Interval scheduling variants
Adapting interval scheduling to different constraints.
One example of an interval scheduling variant that can be solved using dynamic programming is the weighted interval scheduling problem. Each interval has an associated weight in this variant, and the goal is to maximize the total weight of selected non-overlapping intervals.
Here is a brief description of the problem:
Given a set of intervals, where each interval [start_time, end_time] has an associated weight, find a subset of non-overlapping intervals that maximizes the total weight.
The dynamic programming approach involves sorting the intervals by their finish times and then defining a table to store the maximum weight achievable up to each interval. The recursive formula for calculating the maximum weight at each interval is as follows:
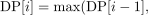

where is the last non-overlapping interval before
Here is a Python implementation of the dynamic programming solution:
In this example, a tuple represents each interval (start_time, end_time, weight). The function weighted_interval_scheduling calculates the maximum total weight using dynamic programming.
Trade-offs
What are the trade-offs involved in choosing between greedy and dynamic programming approaches for different problems?
Both techniques solve optimization problems, but they fit different scenarios. Below, I listed a set of steps to help determine which approach is best.
Greedy approach
- Advantages:
- Efficiency – Greedy algorithms are often more efficient than dynamic programming because they make locally optimal choices at each step without considering the global picture.
- Simplicity – Greedy algorithms are generally easier to conceptualize and implement. They follow a straightforward strategy of making the best choice at each step.
- Disadvantages
- Optimality – Greedy algorithms may not always yield globally optimal solutions. Making the locally optimal choice at each step might lead to a suboptimal overall solution.
- No backtracking – Greedy algorithms make decisions based on current information without revisiting them. Once a decision is made, it cannot be reconsidered, leading to suboptimal results.
- Applicability
- Greedy algorithms are suitable for problems where a series of locally optimal choices leads to a globally optimal solution.
- Examples include the activity selection (interval scheduling) problem, Huffman coding, and coin change with canonical coin systems such as U.S. coins (1, 5, 10, 25). For arbitrary denominations, greedy coin change can fail: with coins 1, 3, and 4, greedy makes 6 as 4 + 1 + 1 (three coins) instead of 3 + 3 (two coins), which is why coin change is solved with dynamic programming above.
Dynamic programming approach
- Advantages
- Optimality – Dynamic programming ensures the solution’s optimality by considering all possible subproblems and avoiding redundant computations.
- Versatility – Dynamic programming applies to many problems, including overlapping subproblems and optimal substructure.
- Disadvantages
- Computational complexity- Dynamic programming can be computationally expensive, especially when many overlapping subproblems exist. Memoization or tabulation is often used to mitigate this issue.
- Complex implementation – Dynamic programming solutions can be more complex to design and implement due to the management and storage of intermediate solutions.
- Applicability
- Dynamic programming is well-suited for problems with optimal substructure, where the optimal solution to the problem can be constructed from optimal solutions to its subproblems.
- Examples include the knapsack problem, shortest path problems, and sequence alignment.
🌸👋🏻 Enjoying this post? Get the next issue of [ret]2read. Once a month, I’ll email you whatever’s on my mind, usually Apple security research, offensive security, open source software freedom, and operating system internals.
Choosing between greedy and dynamic programming
- Nature of the problem
- Dynamic programming is a more suitable choice if the problem exhibits optimal substructure and overlapping subproblems.
- A greedy approach may be more appropriate if the problem can be solved by making a series of locally optimal choices.
- Time and space complexity
- Consider the computational resources available. If efficiency is critical and the problem can be solved greedily, a greedy approach might be preferred.
- Dynamic programming may be better if computational resources allow it and the problem demands an optimal solution.
- Trade-off between optimality and efficiency
- Assess the importance of obtaining the globally optimal solution versus quickly achieving a reasonably good solution. The trade-off often lies between optimality and efficiency.
In short, the choice depends on the problem and how much optimality you will trade for speed.
Usage in computational finance
Almost every field uses greedy and dynamic algorithms. Here is how hedge funds use them to optimize investment strategies.
- Portfolio optimization
- Greedy algorithms help iteratively select assets for a portfolio based on specific criteria, such as maximizing returns or minimizing risk. The result may not be globally optimal, but it is often close enough.
- Dynamic programming can optimize portfolio rebalancing over time. By breaking the problem into subproblems and solving them recursively, dynamic programming accounts for the impact of each decision on the whole.
- Risk management
- Greedy algorithms can assist with risk management by iteratively adjusting positions or portfolio weights to minimize specific risk factors. For example, these algorithms can help manage exposure to market volatility or other risk metrics.
- Dynamic programming can assist in optimizing risk management strategies over time, considering changing market conditions and adjusting risk parameters.
- Algorithmic trading
- Greedy algorithms can aid in algorithmic trading to make quick and locally optimal decisions at each step. For example, in high-frequency trading, these algorithms can optimize trade execution by minimizing transaction costs or maximizing order fulfillment.
- Dynamic programming fits trading strategies built on sequential decisions, since it weighs how each decision affects future actions.
- Option pricing and hedging
- Dynamic programming is commonly used in derivatives pricing, especially for American-style options, where the optimal exercise strategy may depend on the evolving market conditions.
Note
Applying these algorithms at hedge funds takes sophisticated mathematical models, large datasets, and significant computational resources. Hedge funds employ quantitative analysts (quants) and data scientists who specialize in developing and implementing these algorithms.
Conclusion
Greedy algorithms make locally optimal choices at each stage, while dynamic programming algorithms break problems into overlapping subproblems and store solutions to avoid redundant computations.
At hedge funds, greedy algorithms handle real-time decisions, while dynamic programming optimizes portfolios and risk management strategies.
If you enjoyed this post on greedy and dynamic algorithms, consider reading Using Master Theorem Components and Formulations.
